How do you scale a lending business when every single contract requires manual data entry?
That's a rhetorical question.
Up until recently, one consumer lending company used to manually process hundreds of PDF contracts, delivery receipts, and email uploads every single week.
Their staff had to open every document by hand just to read the handwritten or digital fields. From there, they manually matched the contracts with the receipts, renamed the files, extracted the data into spreadsheets, and finally typed everything into their loan management system.
This process was incredibly slow, prone to errors, and simply did not scale.
That's not the way.
I was tasked with solving this, and I love a challenge.
I designed and built a complete two-phase system that automates their entire workflow.
Phase 1 does all the heavy lifting. This means classifying documents, running OCR (Optical Character Recognition), extracting raw data, and pairing contracts with their correct receipts.
Phase 2 acts as the brain of the operation. It takes that extracted data, cross-references it with the company's existing loan database, applies their specific business rules, and automatically generates XML files for direct import into their Nortridge Loan System.
The results of this automation speak for themselves.
- 99%
- matching accuracy
- 1.5-3 min
- per batch
- Down from 30+ min manual
- 50+
- production releases
What Was the Context?
Picture this.
My client is a US consumer lending company. Their business revolves around purchasing installment contracts from various food service and appliance dealers.
And so, every day, these dealer offices send batches of new contracts and delivery receipts to them via email, and each batch contains a messy mix of different formats.
They get:
- Handwritten contracts, mostly single-page documents that are photographed or scanned.
- Digital contracts, meaning electronic, multi-page PDFs that contain credit applications, ACH (Automated Clearing House) forms, and multiple different contract types.
- Delivery receipts, which are often just scanned images inside PDFs, or paperwork photographed with smartphones.
- Outlook emails in the form of standard .msg files that serve as an index of what the batch actually contains.
Before my system entered the equation, their employees had to manually process all of this.
It looked something like this:
- They would open each PDF and figure out the document type.
- Then, they had to read the buyer names, co-buyer names, amounts, payment terms, product descriptions, etc.
- Next, they matched each contract with its corresponding delivery receipt and combined those matched documents into a single PDF using strict naming conventions.
- Finally, they entered all the extracted data into a spreadsheet, logged into the loan management system, and manually created or updated the loan accounts.
This entire routine took over 30 minutes per batch, and that's for an experienced employee. And, no matter how experienced you are, mistakes were very common, especially with handwritten contracts, because traditional OCR is unreliable by nature.
So, What Was My Role?
I was the Full-Stack Engineer and Consultant for this project.
I owned the entire technical scope from start to finish.
This included the system architecture and technology selection. I handled backend implementation using FastAPI, PostgreSQL, Celery, and Redis. I also designed the OCR and AI pipeline using Google Document AI and the OpenAI Vision API, alongside a custom matching algorithm.
For the user interface, I built the frontend using React, TypeScript, and Tailwind CSS. I also designed the rule engine for Phase 2, managed the deployment and infrastructure using Railway and Docker, and collaborated directly with the CEO to refine requirements, map out edge cases, and plan iterative improvements.
What Does the System Architecture Look Like?
The platform consists of a FastAPI backend and a React frontend, which are connected through a REST API. All of the heavy processing, such as OCR, AI extraction, and PDF generation, runs asynchronously. This is handled using Celery workers with dedicated queues for different types of workloads.
Here's a clear diagram that explains everything.
What Does the Data Model Look Like?
The core data model tracks the lifecycle of every processing job, right from the initial upload through to the extraction and output generation.
Analysis Job
├── Analysis Files (uploaded PDFs, images, emails)
│   ├── Analysis Pages (per-page status and renders)
│   ├── Analysis Results (extracted fields as JSON)
│   └── OCR Results
├── Analysis Matches (contract-receipt pairings)
├── Analysis Outputs (generated combined PDFs)
├── Extracted Rows (structured data for XLSX)
└── Analysis Logs (event tracking)
Phase 2 then adds an entirely separate data layer specifically designed for loan processing logic:
Snapshot (daily NLS database import)
├── Loan Accounts
└── Contacts

Purchase Case (materialized from Phase 1 extraction)
├── Purchase Contracts
├── Proposed Actions (new account, reorder, transaction)
└── Audit Log

XML Batch (generated for NLS import)
How Does the Phase 1 Processing Flow Work?
When a user uploads a batch of files, the system immediately executes a structured processing pipeline.
Here is a step-by-step breakdown of how that pipeline handles the incoming documents:
- Upload Files: The system accepts emails (.msg/.eml), PDFs, and standard images (PNG/JPG).
- Classify Files: It determines the file type, extracts any PDF attachments, and parses the email text.
- Detect Format: It checks if the document is digital or handwritten, and converts it to a standard PDF if necessary.
- Extract Text: The system runs the multi-strategy OCR fallback chain.
- Extract Fields: It pulls the required data points directly from the text.
- Bipartite Matching: The algorithm pairs the contracts with their correct delivery receipts.
- Output: Finally, it generates the combined PDFs, creates the XLSX report, and uploads everything to storage.
Why Did I Choose a Multi-Strategy OCR Approach?
The hardest part of this project was achieving reliable text extraction across wildly inconsistent document quality.
We were dealing with handwritten contracts filled out with a pen and scanned at various resolutions. Sometimes, they were even photographed at odd angles.
We also had digital contracts with embedded forms and varying layouts across different dealer offices. On top of that, the delivery receipts were frequently just smartphone photos of signed paperwork.
Absolutely no single OCR strategy can handle all of these variations well. My solution was to build a robust fallback chain that looks something like this:
- Digital text extraction (PyMuPDF): The system first tries to extract text directly from the PDF layer. If the PDF contains selectable text, this extraction is instant and perfectly accurate.
- Google Document AI: For scanned documents, the system falls back to Google's OCR service. This handles printed text and moderately clean handwriting very well.
- OpenAI Vision (GPT-4o): For pages where Document AI fails or returns low-confidence results, the system triggers the final fallback. It renders the page as an image and sends it to GPT-4o's vision capability with a highly structured extraction prompt.
The most important thing here is that every single page is processed independently. If one page fails, the others continue without interruption.
For example, in a 15-page contract batch, having one badly scanned page should never block the other 14 pages from processing correctly.
How Does Bipartite Matching Work?
Matching contracts to delivery receipts sounds simple in theory, but it gets complicated quickly when you account for real-world variations.
For example:
- Buyer names are sometimes misspelled on one document but spelled correctly on the other.
- Co-buyer fields are frequently left blank on delivery receipts.
- Sometimes, a single customer can have multiple contracts (like a food contract and an appliance contract) but only one delivery receipt.
- Furthermore, some delivery receipts intentionally have no matching contract, while some contracts have a missing delivery receipt that needs to be flagged.
To handle this chaos, I implemented a bipartite matching algorithm.
It extracts the buyer name, co-buyer name, and ship-to names from both the contracts and the receipts. It then computes similarity scores using configurable thresholds (MATCHING_MIN_SCORE and MATCHING_MIN_GAP) to produce the optimal pairings.
Whenever the OCR confidence is low, the system uses the email body text as a supplementary signal to help resolve the names accurately.
Why Are Emails Used as a Contextual Signal?
Early on in the project, the client suggested using the email that accompanies each batch as a sort of index. This turned out to be one of the most valuable signals in the entire system.
Typically, the email subject contains the date and the office name. The email body usually lists each customer alongside their order type. The system parses these .msg and .eml files, extracts this structured context, and uses it to do several things:
- First, it can automatically fill in the office name for the output filenames.
- It also uses this email data to resolve ambiguous buyer names from poorly scanned contracts.
- It can then identify expected items when the contract field is illegible or blank.
- Finally, it can accurately distinguish between an expected unmatched receipt versus an actually missing document.
What Does the Final Output Look Like?
For every matched group, the system automatically generates a few key deliverables.
The company gets:
- A combined PDF that follows a strict naming convention:
Date - Office - Name - Item 1 - Item 2 - DR.pdf - A system flag and individual save file for any unmatched items.
- An XLSX report containing all the extracted fields, their confidence scores, and any necessary review flags.
- A single ZIP download containing all of these files together.
How Does the Phase 2 Rule Engine Work?
Once Phase 1 was stable and active daily, the client introduced a second major requirement.
Instead of having their staff manually enter the extracted data into the Nortridge Loan System (NLS), they wanted to completely automate the decision-making process and generate XML import files directly.
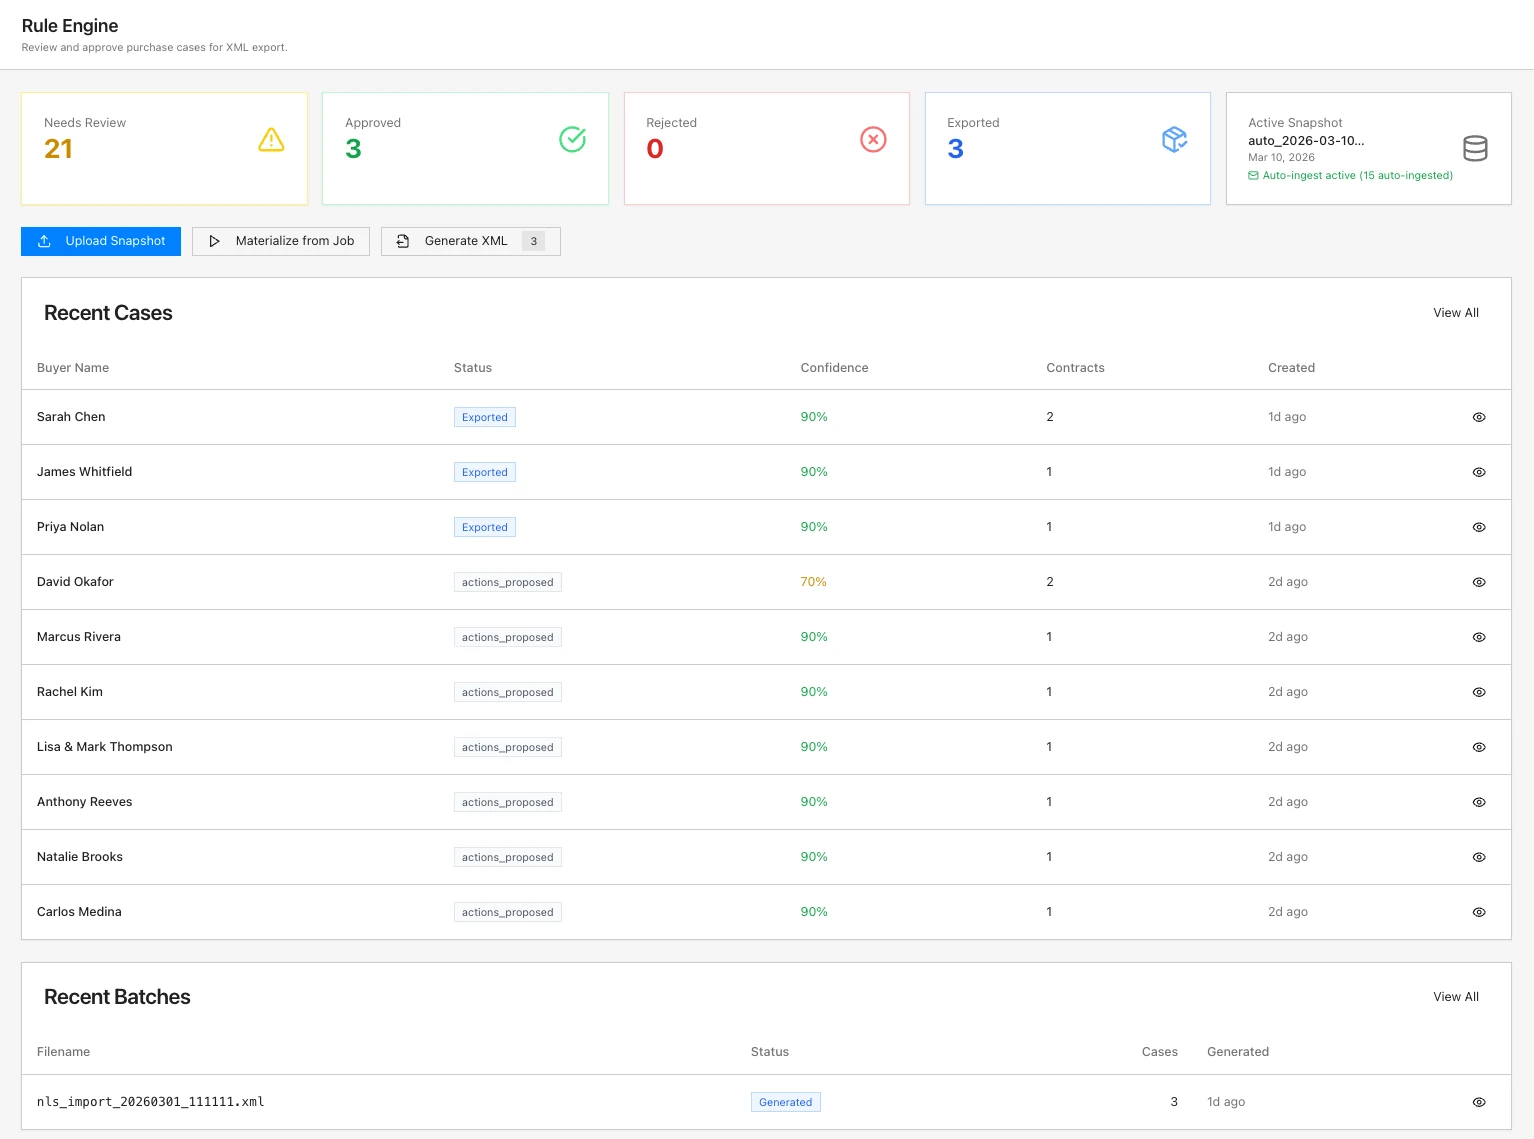
What Is the Business Logic Behind the Engine?
The custom rule engine handles a series of complex decisions for every single extracted contract.
First, it searches the contact report to see if the customer is already in the system. If the customer is not found, it flags them for a manual new customer setup.
If the customer is found, it searches the loan report to check for an existing food account. Depending on whether it is a food or appliance contract, and whether there is a past-due balance or a positive current principal, the system proposes a specific action.
This could mean creating a brand new loan account, adding an amount and updating the payment schedule for a reorder, or flagging the account for manual review without executing via XML.
Every decision node produces a proposed action that the user needs to review before the final XML generation.
The system also computes risk ratings, validates contract math (such as verifying that months multiplied by payment equals the amount financed), and handles specific office rules for different dealer territories.
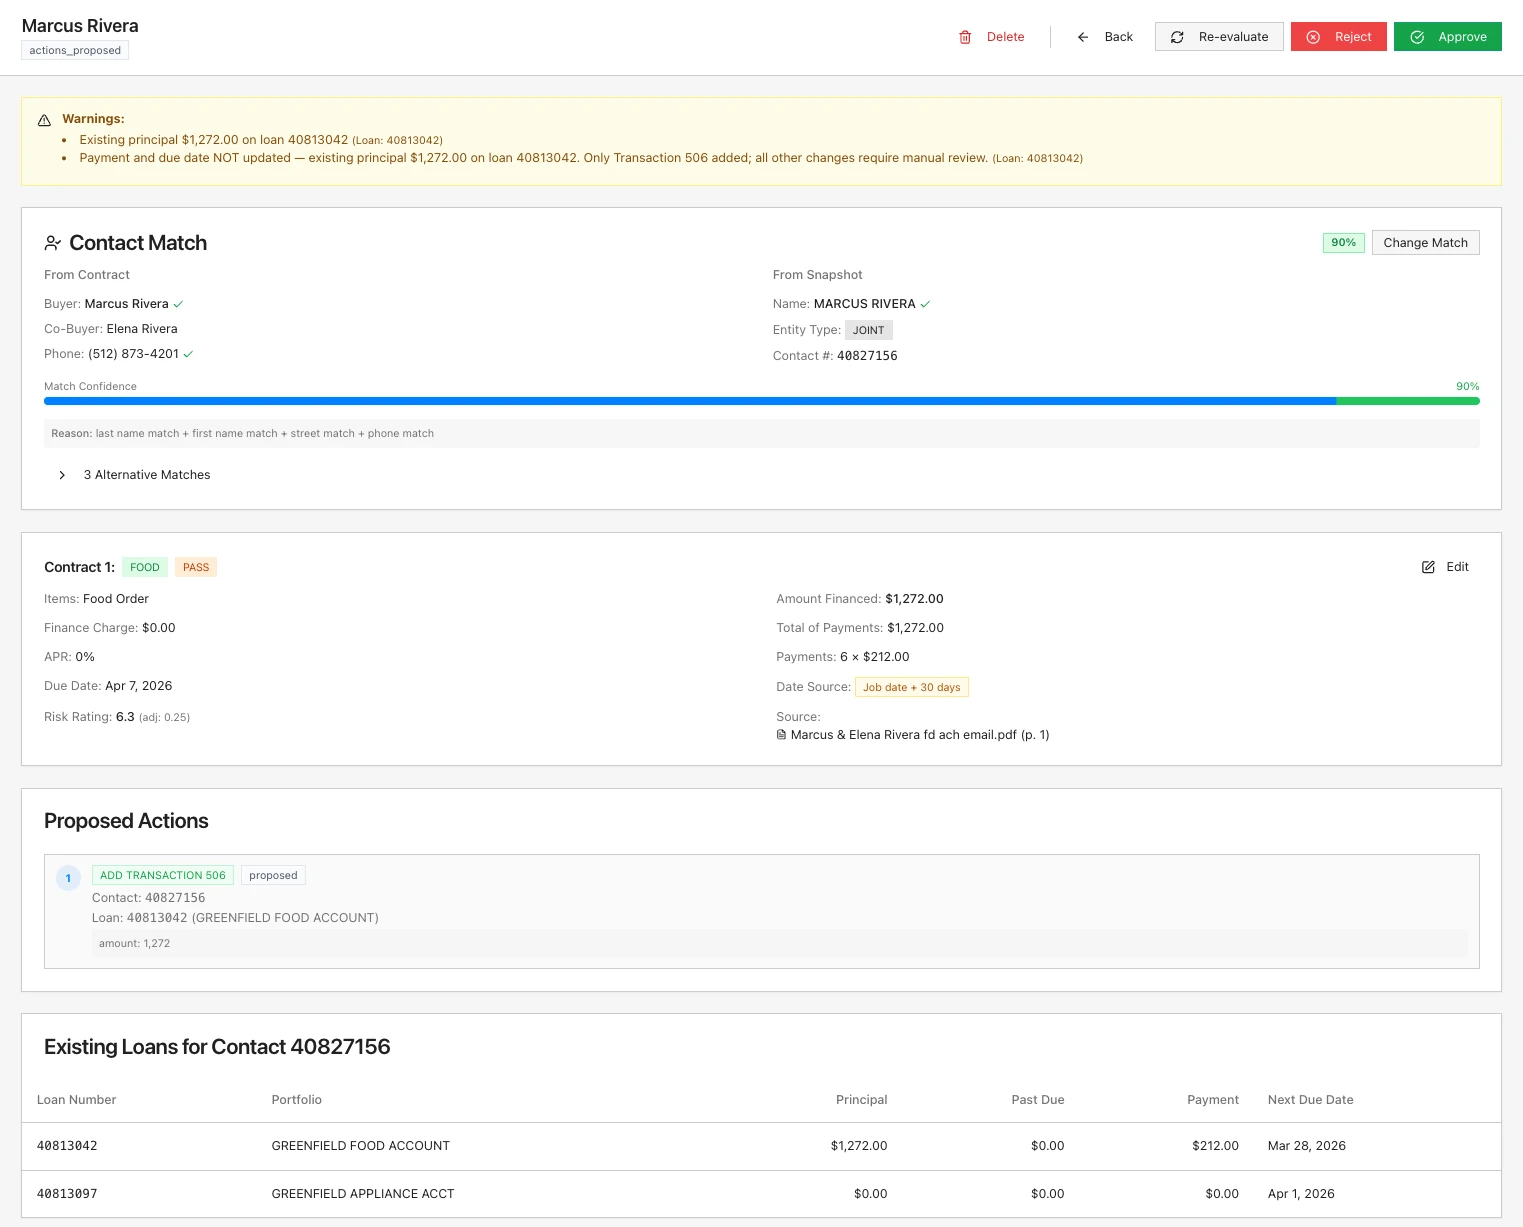
How Is the Loan Database Managed?
Rather than requiring the staff to manually upload the loan database, the daily export from the loan system is ingested automatically on a set schedule. Because of this, the database snapshot behind the matching process refreshes itself, and the staff never has to upload it by hand.
How Are the XML Files Generated?
The final output of Phase 2 is an NLS-compatible XML batch file.
This file contains all the necessary loan creation records, transaction codes for reorders, and payment schedule updates. Each batch is strictly isolated per user session. This means that two employees can easily work simultaneously without any cross-contamination of their data.
How Did I Make the System Production-Ready?
Once both phases were running, my actual work shifted from just "building features" to "making a system that non-technical staff could trust with real money."
A consumer lending pipeline cannot just be fast. A wrong loan amount or a silently dropped account represents a very real financial event.
Because of this, most of my engagement after the launch focused on building strict safety nets, deep observability, and a robust test suite that pins down every bug that ever reached production.
Here is how I hardened the system:
Pre-export validation
Before any XML batch ships to the loan system, a validator sanity-checks every single loan record. This covers amounts, terms, payment math, and field lengths (because NLS rejects user-defined fields over 50 characters).
It then surfaces errors and warnings inline.
Reviewers can then run a "Preview XML" dry-run on a per-case basis, or validate an entire batch in the Generate Batch flow to see exactly what would fail before anything reaches NLS.
Import reconciliation
After a batch is imported, the staff records how many loans NLS actually accepted. The system compares the sent-versus-accepted numbers and flags any gap on the batch list and a dashboard health card.
This ensures a loan that silently fails to import cannot just disappear unnoticed.
Snapshot staleness guards
The matching process runs against a daily snapshot of the loan database.
If that snapshot is older than a configurable threshold, the case detail displays an amber warning. That way, reviewers never trust a match made against stale data.
Incident-driven regression suite
Every production bug was turned into a named test. Whether it was a misparsed generational name suffix, a due-date rule that went silent, or a v1/v2 extractor merge that dropped line items, they are all tracked and logged.
End-to-end "golden" tests run extracted-row fixtures through the full rules-to-XML chain to cover complex co-borrower and multi-contract cases.
So, the bugs that were fixed once will stay fixed.
Observability and a self-auditing cron
Each pipeline boundary emits one greppable, event-tagged log line, like rule evaluation, materialization, XML generation, and batch lifecycle.
A weekly audit job re-scans for whole classes of silent regression, and it only emails the team when it finds a new affected contract.
Here's something that actually happened.
When an upstream OpenAI billing outage took the extraction down mid-day, I diagnosed and restored it the very same day. Then, I shipped fixes for a missing endpoint that surfaced during the incident.
The system is run entirely by non-technical staff, so my engineering exists strictly to keep everything boring and predictable for them.
Why Did the Project Pivot to a Web Application?
The project initially started as a Windows desktop application.
However, after building the initial prototype, I strongly recommended pivoting to a web application.
Here is why I pushed for that change:
- Maintenance: Desktop apps require distributing and installing updates on every individual device. Web updates are instant and completely transparent.
- Environment consistency: Windows applications are highly sensitive to OS versions, permissions, and local antivirus configurations. A web app eliminates all of those unpredictable variables.
- Onboarding: Adding new team members to a web app requires no software installation.
- Architecture alignment: All the heavy processing is done in a backend service. The desktop app was just a thin client, while a standard web browser does that exact same job with far less friction.
The client agreed with this pivot. Because the core processing logic was already safely isolated in the backend, the pivot required almost no rework. Also, the early architectural decision to keep the UI layer thin paid off immediately.
What Were the Final Outcomes?
- Processing time: Batches of 6 to 15 mixed documents are now complete in just 1.5 to 3 minutes, down from 30+ minutes of manual work per batch.
- Matching accuracy: The system achieves a 99% success rate on contract-receipt pairings across both handwritten and digital formats.
- Daily production use: The system safely processes real document batches every single business day, operated entirely by non-technical staff with no developer interventions.
- Phase 2 operational: The rule engine matches extracted contracts against the loan database and successfully generates NLS-compatible XML files for batch imports.
- Automated ingestion: Daily loan system snapshots are ingested automatically, which eliminates all manual data uploads.
- Reviewer safety net: Pre-export validation, batch import reconciliation, and snapshot-staleness guards reliably catch financial-impact errors before the XML ever reaches the loan system.
- Hardened over time: A growing regression suite and end-to-end golden tests pin down every production incident, backed by a weekly self-audit cron and event-tagged observability across the entire pipeline.
My Key Reflections
Design for the document, not the happy path
The biggest source of bugs was the assumption that documents would be consistent, when they simply weren't.
Handwritten contracts vary wildly, and scans are often cropped, rotated, or low-resolution.
The system needs to handle every variation gracefully, and not just the clean samples provided during the discovery phase.
Fallback chains beat single-strategy bets
Not a single OCR technology handles every document type perfectly. Chaining PyMuPDF, Document AI, and OpenAI Vision together with per-page fault isolation made the system more resilient.
The email is not just metadata
The email that accompanies each batch initially seemed like a secondary signal, but became one of the most important inputs for name resolution, office identification, and missing document detection.
Always listen closely to domain experts when they suggest something that might be useful.
Non-technical users will find every edge case
Building in a mandatory review step for low-confidence extractions saved the system's credibility with the end users. Every week revealed new document formats, naming quirks, and workflow assumptions that were invisible during development.
Speed gets you launched, but safety nets keep you in production
The hardest and most valuable work came after the system was technically "done."
In a business where a wrong number represents a real financial event, validation gates, import reconciliation, and an incident-driven regression suite are exactly what encourages non-technical staff to trust the system with real money every day.
Separate processing from decision-making
Phase 1 (extraction) and Phase 2 (rule engine) are architecturally independent.
Phase 1 produces clean, structured data, while Phase 2 consumes it and applies business rules.
This clear separation meant Phase 2 could be designed and built after Phase 1 was stable in production, without modifying the extraction layer.
Today, the system is in active, daily use, reliably processing document batches for a consumer lending operation every single business day.